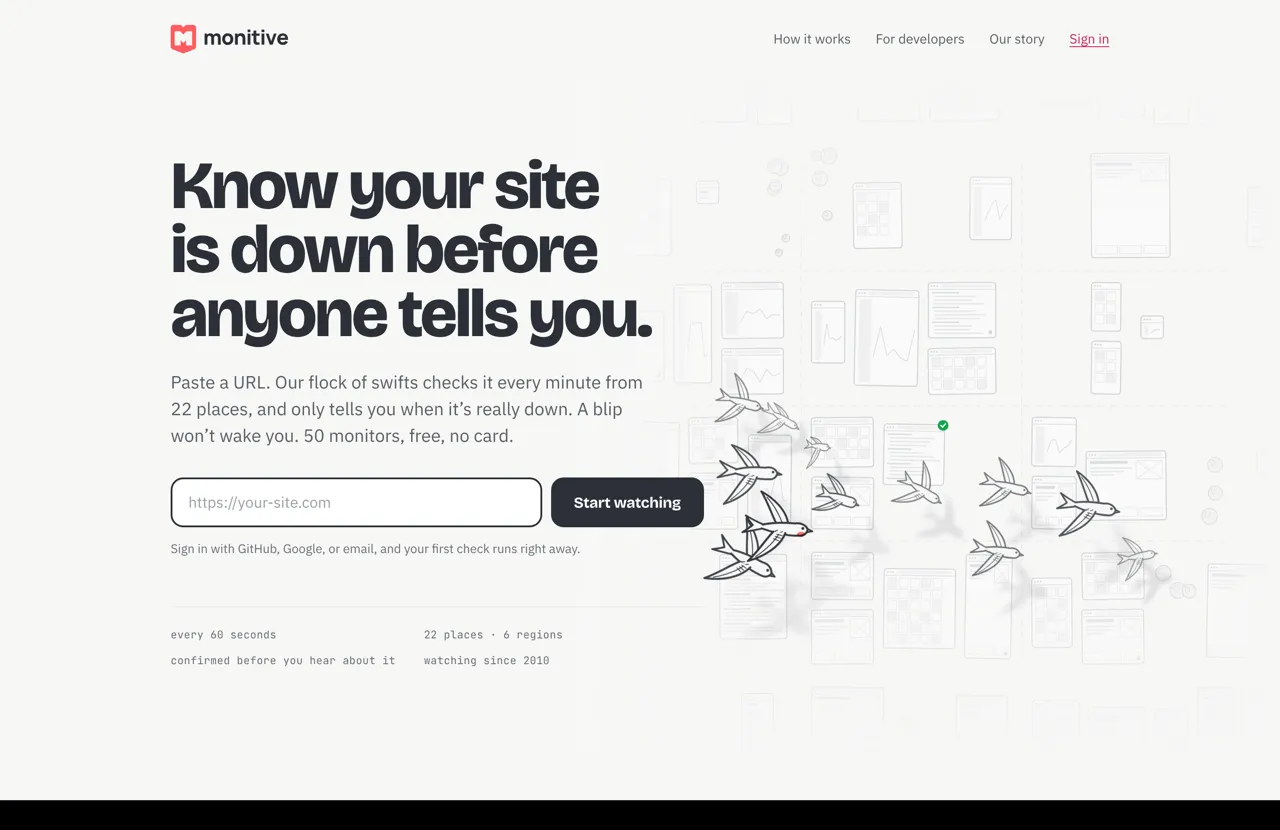
Know your site is down before anyone tells you.

Paste a URL. Our flock of swifts checks it every minute, and only tells you when swifts in other regions agree it’s down. A blip won’t wake you. 50 monitors, free, no card.

Sign in with GitHub, Google, Microsoft, or email, and your first check runs right away.

every 60 secondsfrom six regionsconfirmed before you hear about itwatching since 2010

Know the feeling?

Four things that happen to people who run something on their own. We’ve had every one of them.

  • A customer emailed to ask if I knew the site was down. It had been down for an hour.

  • My phone went off in the middle of the night for a thirty-second blip that fixed itself before I’d found my glasses.

  • I’ve meant to put up a status page since the week I launched. It’s still on the list.

  • The deploy went fine. The site didn’t. Nobody looked until the morning.

How it works

A flock that never lands.

  1. 01

    Every minute, a swift checks your site.

    Checks come from six regions. When one says you’re down, others check before anyone tells you.

  2. 02

    If one sees a problem, the others go and look.

    Swifts in other regions check again before anything changes. Every one of those checks is kept with the incident: what failed, from where, and how long each step took.

    06:01:19  SA    HTTP 521, expected 200
    06:01:24  EU    HTTP 521, expected 200
    06:01:31  US-W  HTTP 521, expected 200
    06:01:31  confirmed by 3 of 3 · incident opened
  3. 03

    You hear about it once.

    One alert, with what we saw, and one more when your site is back.

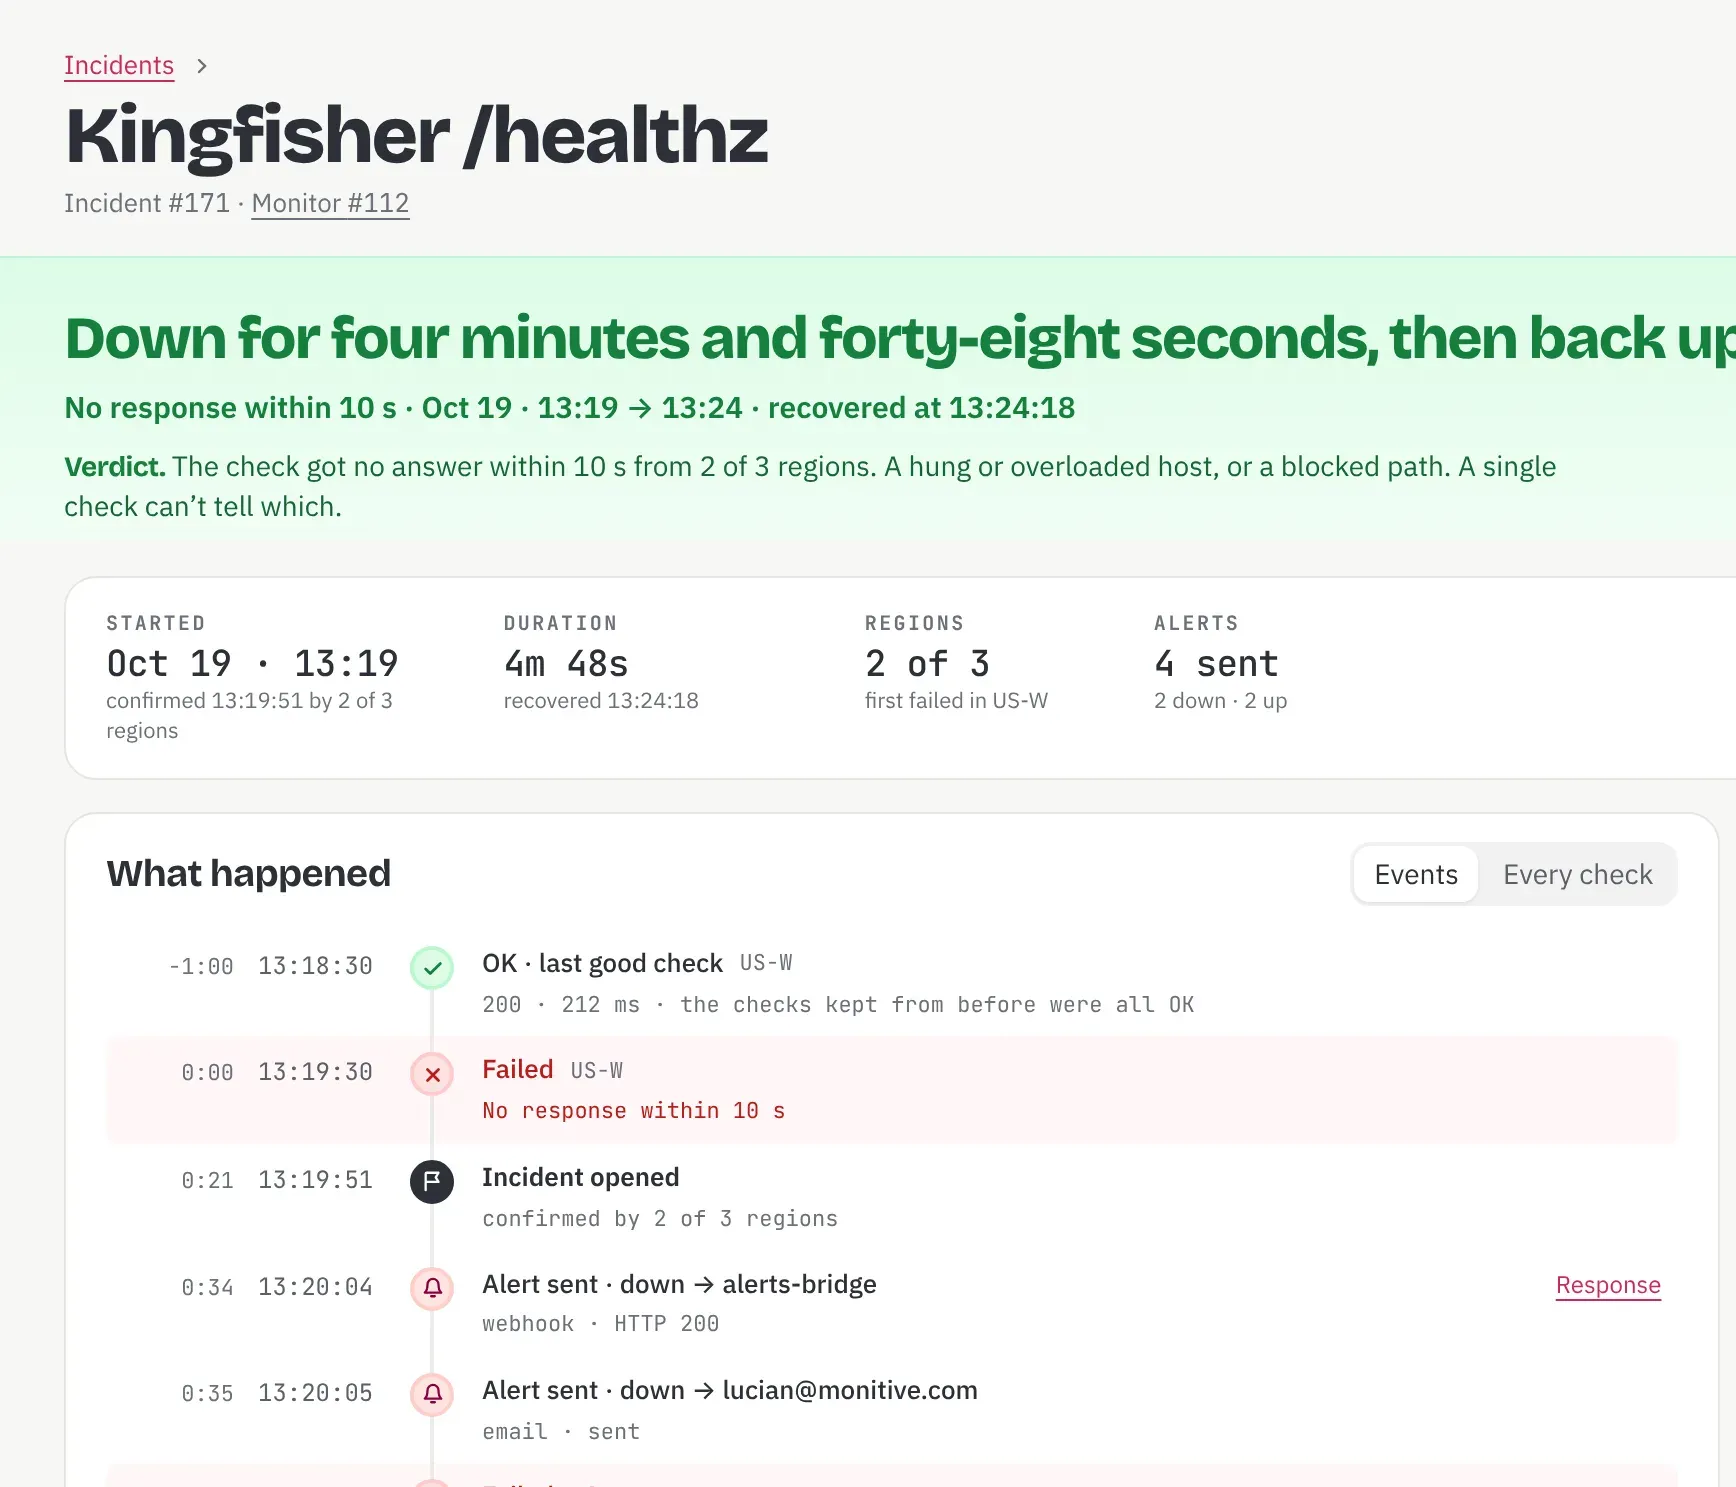
An incident in Monitive: Down for four minutes and forty-eight seconds, then back up. Confirmed by 2 of 3 regions, 4 alerts sent, with the timeline of checks and alerts.
A real incident, start to finish: first failure, confirmation from a second region, the alert, the recovery.

What it watches, and how it tells you.

The usual things, done properly, and nothing you have to configure before the first check.

It watches

  • HTTP and HTTPS, with your own method, headers and body, and a check that the page says what it should.
  • TCP ports, for the database, the mail server, anything that listens.
  • Ping, for the box itself.

It tells you by

  • Email, by default.
  • Slack, to the channel you pick.
  • PagerDuty, if that’s where you’re on call.
  • Webhooks, for whatever you’ve built.
  • Browser push, on the laptop and the phone.

And it knows when not to

  • A blip won’t wake you: another region checks again before anything is called down.
  • One message when it’s back, so you don’t have to keep refreshing.
  • Test alerts: send yourself one now, so the first real one isn’t a surprise.

For developers

Already in your pipeline.

If you’d rather not click through a form, don’t. Everything on this page can be done from a terminal, a workflow, or an agent.

  • A REST API for monitors, incidents and the evidence behind them. One request creates a monitor; the response is the monitor.
  • An MCP server for Claude Code and Cursor, so an agent can watch what it just shipped.
  • A GitHub Action that fails the deploy when the site isn’t healthy afterwards. The next step never runs on a broken site.
REST ·
curl -X POST https://api.monitive.com/api/v1/monitors \
  -H "Authorization: Bearer mk_live_…" \
  -H "Content-Type: application/json" \
  -d '{"name":"Shop",
       "url":"https://shop.example.com",
       "type":"http",
       "interval_sec":60}'
MCP · Claude Code
› watch shop.example.com and tell me if it goes down

⏺ create_monitor(name: "Shop", url: "https://shop.example.com",
                 type: "http", interval_sec: 60)
  ⎿ {"monitor":{"id":12,"name":"Shop",…},"state":{"status":"up",…}}

⏺ Done. Shop is monitor 12, checked every
  minute. If it’s really down, you hear first.
GitHub Action · .github/workflows/deploy.yml
# after your deploy step
- name: Make sure it’s really up
  uses: monitive/assert-healthy@v1
  with:
    api-key: ${{ secrets.MONITIVE_API_KEY }}
    # the monitor’s numeric ID, e.g. 12
    monitor-ids: ${{ vars.MONITOR_ID }}

Everything above, and the rest: Docs · Developers

Show your customers.

The status page you kept meaning to make is already made. Add the badge to your footer, and let people subscribe to the feed instead of emailing you.

  • A public status page for each monitor, free, with the incidents it’s had.
  • An uptime badge for your footer or your README.
  • RSS and Atom feeds of incidents, for the people who’d rather subscribe.
  • Weekly and monthly reports, so you see the month, not just the night.
  • Team members and roles, when it stops being only you.

Our story

Watching since 2010.

We started Monitive in 2010, when a monitor meant a cron job and a hope.

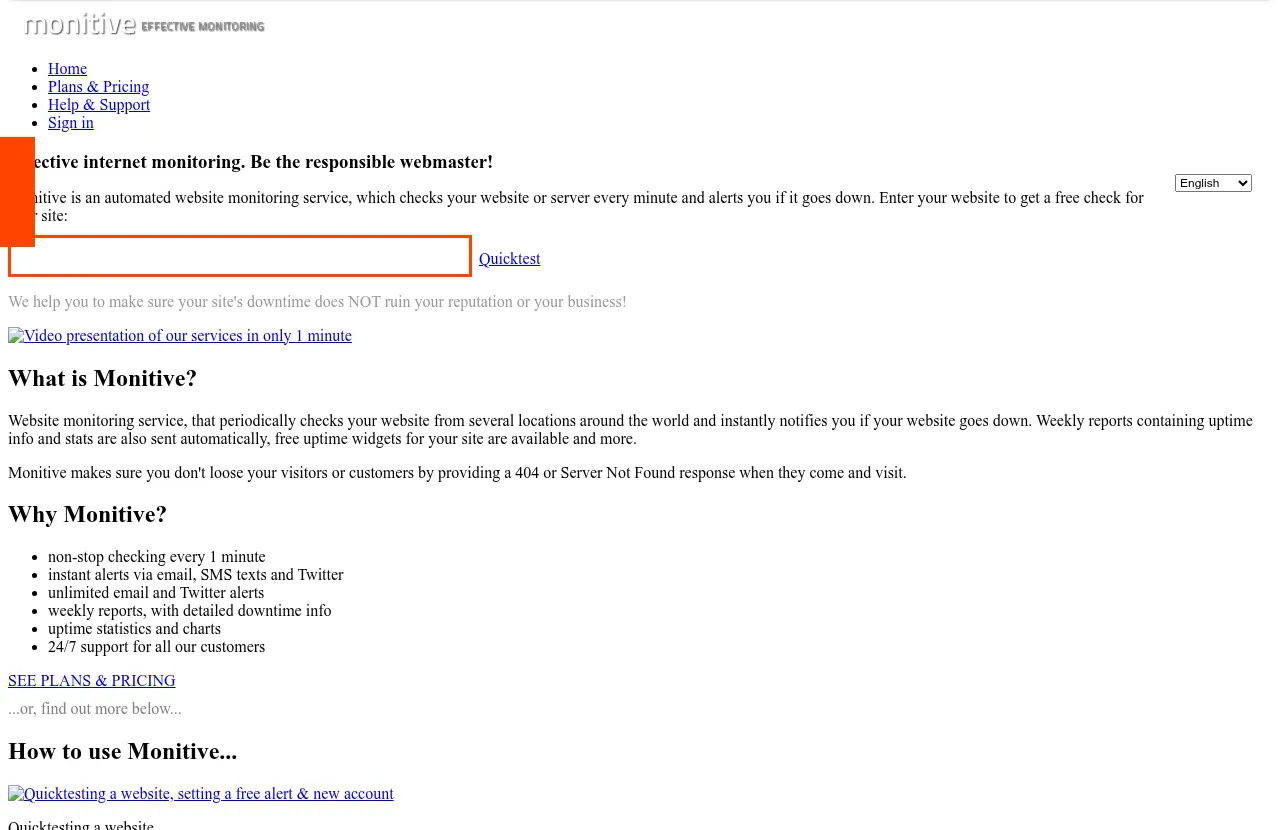
The same promise on our homepage since 2011: tell us your site, and we’ll watch it every minute. The 2014 one even counted checks live on the page. The count has passed two billion since.

We think the next person to paste a URL here might not be a person at all. Agents are starting to set up their own monitoring after a deploy, so we built the API and the MCP server to be as plain as the form above. Whoever shipped it should know first.

Why a swift? Common swifts stay in the air for months at a time. They eat, drink and even sleep on the wing. A bird that doesn’t come down felt like the right one to draw on a page about uptime.

16 yearsmore than two billion checkscheck locations in six regions

“Gives me the peace of mind that I’ll be the first to know.”
Alin T. at Movalio
Monitive homepages from 2011, 2012, 2014 and today
The 2011 homepage: a URL field and a quick test 2011
The 2012 homepage: reliable site uptime monitoring, with a quick-test field 2012
The 2014 homepage: a URL field, Check Now, and a live check counter 2014
Today’s homepage today

Your first monitor takes 30 seconds.

Sign in with GitHub, Google, Microsoft, or email, and your first check runs right away. 50 monitors, free, no card.